Archive for Surfshark

Guest Post: Users risk money and data for $8.53 discount on Netflix, Spotify, and similar plans from unauthorized resellers

Posted in Commentary with tags on October 28, 2026 by itnerd

Despite Netflix’s slowing growth, unauthorized resellers aren’t slowing down. According to the latest Surfshark analysis, reseller subscription prices for Netflix, YouTube Premium, or Duolingo, and other popular platforms average $4.60 per month, compared with $13.13 for official plans. Buying through a reseller costs consumers about 65% less, an average saving of $8.53 a month, or more than $100 a year. However, these deals carry real risks, such as an invalid subscription, lost money, and exposed personal data.

Many reseller offers also require customers to commit for a full year. The analysis found that the shortest available subscription period was 12 months for eight of the 10 services, while the remaining two had a minimum term of six months. These long-term offers create an attractive monthly price, but also expose customers to greater upfront risk. If access to the account is terminated before the subscription ends, customers may have to rely on the reseller to restore the service or issue a refund.

“These pie-in-the-sky offers very often involve trade-offs such as upfront annual payments, shared accounts, reduced access control, and reliance on an intermediary for customer support. Yet nothing guarantees that the promised $100 in yearly savings won’t turn into a $50 loss the next day,” says Tomas Stamulis, Chief Security Officer at Surfshark.

As a rule, shady online offers peak during the shopping season. Tomas Stamulis says the same applies to unverified resellers offering cheap subscriptions. In October, Surfshark customer care recorded a growing number of cases in which people who subscribed to the Surfshark VPN and cybersecurity app through unauthorized resellers lost their accounts and money.

“When users buy subscriptions through unlicensed resellers, they very often end up in a trap. Surfshark itself investigates cases where customers buy too-good-to-be-true deals. Within a day or two, it turns out the subscription has already been used by someone else, and the account is no longer valid. The only way to protect yourself and your money is to buy services directly through official websites or through authorized creators who still redirect you to the official company website to make a purchase,” says Stamulis.

He warns that illegitimate reseller subscriptions often violate the service’s terms or involve fraud. This puts consumers’ money, accounts, and personal data at risk, while also taking revenue away from the official platforms and creators behind the content.

Besides, the checkout process on some reseller platforms requires excessive amounts of user data. One analyzed reseller platform requested customers’ full name, physical address, ZIP code, and email address, while another asked for full name, country, and WhatsApp number. Sharing personal data and payment information with a reseller company may increase consumers’ exposure to data breaches, spam, phishing, and targeted scams.

As the holiday shopping season begins, Surfshark’s CSO warns that consumers will encounter subscription offers of all kinds, and that deals priced far below official plans often mean a shared or stolen account that can be terminated at any moment.

Cybersecurity expert recommends:

  • Buy only from official websites. Subscribe directly on the platform’s website or app, or through authorized partners who redirect you to the official website to pay.
  • Avoid long upfront commitments with unknown sellers. Many reseller offers require you to pay for 12 or at least six months in advance. If the account is canceled, you lose the whole amount.
  • General rule when purchasing online: share as little personal data as possible. A digital subscription does not need your physical address or WhatsApp number. Email masking and a disposable payment card keep your inbox and money safer.

Please find the full research material

here.

Guest Post: Top social media platforms fined $26 billion over privacy violations

Posted in Commentary with tags on October 20, 2026 by itnerd

New Surfshark research finds that 10 of the world’s most popular social media platforms have faced more than $26 billion in privacy-related fines and settlements since 2020 across Europe, the US, Australia, and South Korea.

“These fines and settlements highlight the consequences social media companies can face over how they handle personal data. Some cases have already led to concrete changes, such as making tracking cookies easier to reject. But a bigger penalty does not automatically mean users are better protected, and if platforms treat it as a cost of doing business, the impact may be limited.

The real test is whether these cases drive changes that are implemented and sustained: more responsible data collection, greater transparency, and stronger safeguards, especially for children. The size of the penalty matters, but what it changes for users matters more,” says Dr. Luís Costa, Research Lead at Surfshark.

Since 2020, 10 of the world’s most popular social media platforms have faced more than $26 billion in privacy-related fines and settlements across Europe, the US, Australia, and South Korea.

Meta-owned platforms accounted for 91% ($23.7 billion) of the total, with Facebook alone responsible for $14.3 billion and Instagram for $9.4 billion. TikTok ranked a distant third at $1.6 billion.

Mid-tier totals included LinkedIn ($360 million), YouTube ($222 million), and X ($151 million), while Snapchat ($35 million) and Reddit ($19 million) recorded smaller amounts. Discord registered only $0.9 million, while Pinterest was the only platform with no qualifying fines or settlements identified in the research.

The US imposed the most privacy-related fines

The US imposed a total of $20.9 billion in fines on social media platforms, accounting for 80% of total global fines. The US also issued the largest single penalty in the research, a $17.1 billion settlement with Meta-owned Facebook and Instagram over allegations that inadequate safeguards exposed young users to deliberately addictive platform features.

In addition, US authorities issued fines totaling $3.69 billion for data-processing-related violations. Facebook accounted for $2.9 billion of that amount, followed by TikTok ($593 million), X ($150 million), Instagram ($68.5 million), YouTube ($36 million), and Snapchat ($35 million). TikTok also received a separate $100 million penalty in 2026 for insufficient security safeguards.

European authorities have imposed $5.16 billion in GDPR-related fines on social media platforms, with Ireland accounting for the largest share at $4.87 billion, or 94% of the total. France followed with $245 million, ahead of the UK ($36 million), Spain ($11.6 million), and the Netherlands ($870,000).

Europe’s two largest fines issued to social media platforms resulted from international data-transfer violations. Facebook received a $1.39 billion penalty for transferring EU user data to the US, while TikTok was fined $615 million for transferring European user data to China.

Beyond data transfers, European authorities imposed $1.22 billion in data-processing fines on TikTok ($401 million), LinkedIn ($360 million), Facebook ($244 million), Instagram ($209 million), and YouTube ($11.6 million). Data-breach-related penalties reached $1.09 billion, including $618 million for Facebook, $470 million for Instagram, and $522,000 for X.

EU authorities imposed an additional $594 million in fines for insufficient security, with Facebook accounting for $452 million, followed by Instagram ($106 million), Reddit ($19.3 million), and TikTok ($16.8 million). Cookie-consent violations resulted in $243.6 million in penalties for YouTube ($174 million) and Facebook ($69.6 million), while Discord was fined $928,000 for failing to comply with data-retention requirements.

Among the other analyzed markets, South Korea imposed $62.4 million in data-processing fines on social media platforms, including $43.5 million on Facebook, $11.8 million on Instagram, and $7 million on TikTok.

Meanwhile, Australian authorities fined Facebook nearly $50 million for data-processing violations and imposed a $463,000 penalty on X for insufficient security.

METHODOLOGY

Surfshark examined privacy-related fines and settlements for 10 of the world’s most popular social media platforms, reported in Europe, the US, Australia, and South Korea from 2020 onward. Penalties were grouped by platform, country, and violation type, with a minimum threshold of €200,000 in Europe and $200,000 elsewhere, and converted to US dollars at $1 = €0.87.

Data came from the GDPR Enforcement Tracker, Violation Tracker, Violation Tracker Global, and Osano’s Data Privacy Enforcement Tracker, supplemented by regulatory announcements, court records, and news reports.
Guest Post: People miss 60% of AI bots on social media: the polite ones hide best

Posted in Commentary with tags on September 17, 2026 by itnerd

Surfshark’s analysis of 1,722 participants worldwide shows that people detect only 40% of bot-generated social media comments. The ones people miss most often are positive, friendly, and logic-sounding bots. According to the researcher, positive social media bots can be utilized for social engineering attacks to bypass real users’ defenses.

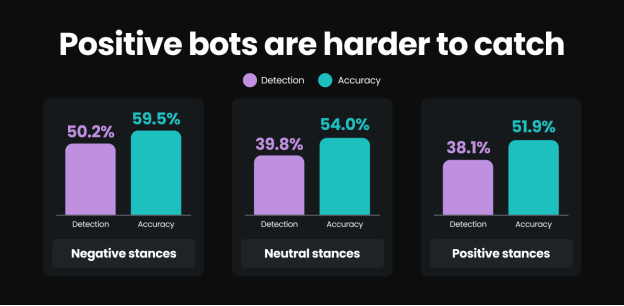
“On social media, everyone notices the angry trolls. That’s why the angry trolls are the ones who often get caught. In the simulated social media environment, participants flagged half (50.2%) of negative AI-generated bots,” said Luís Costa, Research and Insights Lead at Surfshark.

However, when a bot hid behind a positive and friendly persona, participants’ detection rate dropped to 38%, a huge 12-point gap. Besides, the simulation is active online, and you can test your bot detection skills.

“Often, AI-powered accounts used in sophisticated manipulation campaigns are agreeable, logical, or simply unremarkable. They can support real users’ opinions and just inflate the number of comments in the discussion to make a minority view look like everyone feels the same way. Seldom do people report such accounts.”

Surfshark researcher points out that positive and friendly AI bots on social media are considered more dangerous than those that are confrontational and annoying. By being friendly and logical, bots bypass people’s skepticism. You don’t see them as an enemy or a threat, so you are more likely to turn to private chat, share personal information, click a link they share, or believe their “logical” disinformation, which can subtly shift your political and social opinions before you even realize you’re talking to an AI machine.

During the live simulation, one of the biggest red flags was the use of emojis. Bots that used many emojis were caught over 60% of the time, while those that kept communication simple were detected only 35% of the time. This huge 30.6-point gap shows why relying solely on emojis is a bad way to protect yourself on social media. Any scammer who simply stops using an excessive amount of emojis instantly becomes twice as hard to spot.

Users of text-driven platforms led the simulation: X users achieved a 49% bot-detection rate and were the strongest bot hunters, significantly ahead of users from visual- and video-first platforms like TikTok (38%) and Facebook (39%). This means AI bots on TikTok and Facebook are more likely to manipulate real users.

Is it still possible to detect AI-generated content on social media?

Even automated detection tools are struggling to detect AI-generated content. For humans, well-made AI content is now almost indistinguishable from content generated by a real person. Luís Costa, Research and Insights Lead at Surfshark, shares recommendations on what people should do to protect themselves on social media: 

  • Judge the account, not the content. Take a close look at when the profile was created, the profile photo, and what’s written in the ‘About’ section. If you see a brand-new account with a generic photo, a vague bio, and a history of posting the same message over and over, you’ve likely found a fake.
  • Keep in mind that when social media debates get serious, your emotions make you more likely to miss fake accounts and wrongly accuse real people.
  • Don’t assume someone is real just because they’re agreeing with you or being supportive. If you get a ton of generic support really fast, that’s actually easy for a bot to fake. 

In this video, find more security expert’s tips on how to tell a bot from a human on social media: https://www.youtube.com/watch?v=nwuhIfnRKko

“Bot or Not” live simulation, created by Interaction Design students from Malmö University, inspired the launch of Surfshark’s Cybersecurity Advocacy Fund, which provides up to €100,000 in annual financial support distributed among students, researchers, and creative cybersecurity awareness initiatives worldwide. The application process is now open. You can find more information here. 

For complete research material behind this study, click here.

Guest Post: iPhone users can remove 98% of pre-installed apps, Samsung users only 57%

Posted in Commentary with tags on September 8, 2026 by itnerd

The average smartphone user has 60 to 90 apps, using only ~10 daily and ~30 monthly. As a result, 60% to 70% of apps sit unused in the background, collecting personal data. New analysis by Surfshark revealed that bloatware begins with a brand-new phone, as manufacturers load a substantial number of pre-installed apps onto their devices before they reach the user. Samsung leads with 88 preloaded user-facing apps, followed by Google with 71, Xiaomi with 61, and Apple’s iPhone with 50. Interestingly, some of them include third-party apps like Facebook or Instagram that are privacy-invasive, especially when they are never used and just sit in the background.

“Data collection practices by popular applications, particularly social media platforms and chatbots, raise privacy concerns. While certain data points are necessary for basic operational functionality, entities may harvest information for targeted advertising or may even share it with undisclosed third parties. As a result, users are highly recommended to audit installed applications, review permissions, and remove or disable unused apps. Even never-used applications can gather personal data and link to your device,” explains Tomas Stamulis, Chief Security Officer at Surfshark.

Analysis shows that Samsung smartphones come preloaded with apps from Samsung, Google, mobile carriers, and third-party partners. In Bayton’s database of voluntarily synced Samsung smartphones, 88 user-facing apps were logged as preloaded, and 57% of those were marked by the Universal Debloater Alliance Next Generation project as safe to remove and not affecting the phone’s functionality. For example, the iPhone comes with up to 50 built-in apps, all developed by Apple, and EU users can remove up to 98% of them, compared to 88% in other countries.

35 out of 88 pre-installed Samsung apps are available on Google Play, collecting an average of 13 data types per app. This includes location-category data — such as approximate location (14 apps), precise location (12 apps), and physical addresses (11 apps) — among many other types of information.

Facebook and Instagram collect the most data among Samsung pre-installed apps, with each gathering 37 of 38 data types — accounting for 97% of the 38 data types listed on Google Play. Other third-party apps make the list too, including Netflix, Microsoft OneDrive, and Link to Windows, which collect 12, 15, and 6 data types, respectively.

In contrast, an evaluation of 47 of 50 pre-installed iOS apps available on the App Store collects an average of 8 data types. This includes location-category data, such as approximate location (19 apps), precise location (8 apps), or physical addresses (5 apps). It also includes behavioral data, user-generated content, and sensitive information.

Stamulis adds that linking your data to a single ecosystem may be convenient, but those seeking a more privacy-focused approach can minimize data collection by using third-party apps.

“Relying entirely on pre-installed applications can affect your privacy, as apps don’t always protect user data as you might expect. Shifting to third-party alternatives that are privacy-focused can help minimize data collection, limit overall exposure, and reduce unwanted targeted ads. It can also mitigate the risks associated with potential data breaches as your personal data is not stored in a single database.”

Google phones offer the least flexibility for removing pre-installed apps

Bayton’s database shows 71 preloaded user-facing apps on Google smartphones, with 38% identified as safe to remove by the Universal Debloater Alliance Next Generation project. The 40 apps on Google Play disclose an average of 13 data types collected per app, including physical addresses (15 apps), approximate location (14 apps), and precise location (11 apps).

Meanwhile, Xiaomi smartphones have 61 preloaded user-facing apps, with 57% marked safe to remove. There are 33 apps that can be found on Google Play and collect an average of 16 data types, including physical addresses (17 apps), approximate location (15 apps), and precise location (11 apps).

On both Google and Xiaomi smartphones, Google Gemini and the Google app are the most data-hungry, each collecting 29 of 38 data types. However, both manufacturers include apps that claim to collect no data: on Google devices, these include Password Manager, Pixel Screenshots, and Pixel Studio, and on Xiaomi devices – Weather, File Manager, and Mi Browser.

Half of the top mobile apps silently collect browsing history

Posted in Commentary with tags on September 1, 2026 by itnerd

A recent Surfshark analysis shows that 45% of top mobile apps collect information about the websites their users visit. Of the 40 leading Android and iOS apps analyzed across gen AI, social media, e-commerce, and messaging, 18 report collecting browsing history in their app store privacy labels.

Social media collects the most, followed by e-commerce

Nine out of 10 social media apps collect browsing history on at least one platform. Facebook, Instagram, TikTok, X, YouTube, and Pinterest collect it on both Android and iOS. Reddit, LinkedIn, and Snapchat collect it on Android only. Discord was the only social media app that collects it on neither platform.

This data helps platforms build a clearer picture of user interests, target advertising more specifically, and shape in-app feeds based on websites visited outside the app.

Half of the e-commerce apps analyzed collect browsing history on at least one platform. eBay, Shopee, and Shopify collect it on both Android and iOS, while Taobao collects it on iOS only and AliExpress on Android only. The commercial value is direct: the more these apps know about a user’s online interests, the more effectively they can recommend and advertise products. The cost is that browsing habits become increasingly difficult to keep private.

Messaging and generative AI apps also track websites visited

Three messaging apps collect browsing history: Rakuten Viber, Messenger, and LINE. Their parent companies can use this data to build more detailed profiles of users and their interests.

Collection was the least common in the generative AI category. Google Gemini was the only app of the 10 analyzed to report collecting browsing history.

METHODOLOGY

Surfshark analyzed 40 of the most popular mobile apps, 10 each in generative AI, social media, e-commerce, and messaging, selected mainly from Cloudflare’s ranking of the most popular internet services worldwide. For each app, it was recorded whether its Apple App Store privacy label reported collecting “Browsing History” and whether its Google Play Store label reported “Web Browsing History,” then compared results by platform and category. A separate set of browsers was analyzed outside the 40-app sample. For the complete research material behind this study, visit here.

Meta and Google are the most data-hungry Big Tech companies

Posted in Commentary with tags on August 20, 2026 by itnerd

A new study by Surfshark reveals a significant disparity in how the world’s largest technology companies handle personal information. After analyzing 171 Apple App Store apps from Google, Apple, Microsoft, Amazon, and Meta, researchers found that Meta’s apps are the most “data-hungry,” collecting an average of 25 out of 35 possible data types, more than triple the average of Apple (7) or Microsoft (8).

The study analyzed apps across 35 unique data categories, ranging from precise location and browsing history to purchase data linked to user identity. Company averages varied widely: Meta’s apps collected 25 data types on average, followed by Google with 17, Amazon with 12, Microsoft with 8, and Apple with 7. The sample included 44 Google apps, 41 Apple apps, 40 Microsoft apps, 34 Amazon apps, and 12 Meta apps.

The seven most data-hungry apps in the study were all developed by Meta. Meta AI collected 33 data types, followed by Meta Horizon, Meta Business Suite, Meta Ads Manager, Messenger, Forum, and Facebook with 32 each. Notably, all of this data is linked directly to the user’s identity.

Google dominates TOP 40 ranking while Microsoft and Apple remain the least data-hungry

Google accounted for 29 of the 40 most data-hungry apps in the study, compared with 9 from Meta and 2 from Amazon. Google apps in that group collected between 18 and 26 data types each. Although Google’s apps collected fewer data types on average than Meta’s, its presence across the ranking highlights the scale of data collection throughout its extensive app ecosystem. Meanwhile, Amazon Alexa was the most data-hungry non-Meta app, collecting 28 data types.

Microsoft and Apple consistently ranked as the least data-hungry developers across app categories. Microsoft ranked either the least or second-least data-hungry developer in most categories, with the lone exception of Graphics & Design. Apple covered the widest range of categories (15 in total) and consistently ranked as the least data-hungry developer. For example, Apple’s 13 Utilities apps collected an average of 6 data types, compared with 17 for Google’s Utilities apps.

To see a more detailed profile of each Big Tech company, please see the blog post: https://surfshark.com/research/study/big-tech-data-collection  

$1.40 for fake engagement on social media isn’t the issue. It’s our naive attitude to scams

Posted in Commentary with tags on August 4, 2026 by itnerd

Have you ever been drawn to an advertised product when reviews and comments were all positive, with a good user experience, and a large number of views? You have most likely been tricked into content that has been boosted with fake engagement. Surfshark has revealed the true cost of fake popularity on social media, showing how genuine public interest can be overshadowed by fake engagement for just $1.40, and warns that views, comments, or followers do not confirm content legitimacy.

Chief Security Officer at Surfshark, Tomas Stamulis, explained that the primary issue is not the low cost of fake engagement itself, but rather our own naive attitude and lack of skepticism when browsing online. We often interact with and plainly trust ads or pages without recognizing them as potential scams because our mindset is not yet set to filter content and actively search for identifiers that verify legitimacy.

Surfshark’s analysis shows a clear pattern that fake views on social media posts are the cheapest form of engagement across all analyzed platforms. Prices range from $1.40 per 1,000 views on TikTok to $6.70 per 1,000 views on YouTube. By contrast, comments are the most expensive form of fake engagement on social media. Based on the available data, the average price for 1,000 comments was lowest on YouTube at $93, followed by Instagram at $104, TikTok at $140, and Facebook at $287.

According to Stamulis, social media spam filters constantly scan for bot interactions and comments. For this reason, AI, combined with human input, is needed to ensure uniqueness. As a result, when encountering high engagement and only positive comments, we should approach it with skepticism and carefully verify the legitimacy of the advertiser or product.

Scammers can fake followers or reposts to trick you

Study shows that shares, reposts, and retweets tend to be the second-most expensive form of fake engagement. TikTok is the most expensive platform on which to purchase fake shares, at $68 per 1,000, followed by Instagram and Facebook at $37 and X at $27. YouTube is an outlier, with shares costing only $17 per 1,000.

Followers and subscribers are also relatively inexpensive to purchase. The advertised price for 1,000 fake followers ranges from $14 to $20 on Facebook, TikTok, Instagram, and X. YouTube is a clear outlier, with 1,000 artificial subscribers costing $78 — more than four times the average price of followers on the other four platforms.

Stamulis shares some tips on how to verify ads or page legitimacy:

  1. Check the follower-to-engagement ratio. A legitimate account should have around 1-5% or total followers as likes. If the account has 500 000 followers, but it gets 200 likes, something is not ok.
  2. Check the actual comments section. Phrases like “Great content!”, “Love this!”, “Amazing post” most likely are fake. Comments posted within the same narrow time window and have similar phrasing can be flagged as fake.
  3. Check the growth history. There are designated tools to check the growth of the account. Sudden spikes in growth can suggest the page has fake engagement.
  4. Analyze followers. Review 10-20 profiles. Bot accounts tend to have similar username formats, account creation dates around the same period, and follow many accounts with few friends.

Guest Post: Meta’s Muse Image release highlights “consent on” crisis in AI training on social media

Posted in Commentary with tags on July 10, 2026 by itnerd

The launch of Meta’s new Muse Image tool has brought renewed scrutiny to a systemic privacy issue: the “consent on” default setting for AI training on social media. This release marks a significant shift from using data for general model improvements to a more personal and potentially invasive application of generative AI.

“While past AI developments mostly worked out of sight, Muse Image changes the game by letting users directly reference public Instagram accounts to create images using data from those posts. This shift turns the ‘consent on’ default into a critical privacy risk, as individuals have no way of knowing when their personal photos are being harvested as source material for someone else’s AI-generated content,” says Luís Costa, Research and Insights Team Lead at Surfshark.

According to a recent Surfshark study, nearly all major social media platforms prioritize AI development over user privacy by default, using active data collection for model training.

The study found that 8 out of the 10 most popular social media platforms set AI training consent to “on” by default. This “opt-out” rather than “opt-in” model means that unless users proactively navigate complex settings and forms to revoke access, their years of posts, photos, and even private interactions have likely already been integrated into training sets.

“If you’ve ever shared content on social media, it’s highly likely that your photos are already being exploited as a resource for AI training without your clear consent. Our findings revealed that because platforms lack user-friendly opt-out options, much of this data usage is effectively irreversible. Opting out today only prevents future collection, but it cannot undo the training that has already occurred,” says Costa.

The issue of using user content for AI training is also highlighted by other social media platforms, most notably Reddit, which offers no option to opt out of AI model training. Its vast forum discussions are openly used for global AI development, highlighted by contracts with Google and OpenAI to license this user-generated data. In contrast, Discord stands out as the singular exception among the 10 platforms examined. It explicitly states that it does not use user data for AI training.

For the complete research material behind this study, click here.

Note that the IT Nerd has covered mitigating this privacy breach here.

Google approved 90% of Play Store submissions, but later removed 2 million apps

Posted in Commentary with tags on June 16, 2026 by itnerd

Last year, Google and Apple removed nearly 2.2 million mobile applications from both stores, highlighting a low rejection rate: 9 out of 10 submissions to Google Play went through. Interestingly, Apple more than doubled its total App Store removals, surpassing 166,000, with fraud accounting for 54% of those removed (90,608). In contrast, Google saw a significant decline in total removals, from 3.9 million to 2 million, and its fraud-related deletions dropped to only 5% of its total removals.

Surfshark’s analysis shows that in 2025, Apple rejected 23% of submissions to the App Store, whereas Google Play’s rejection rate was nearly three times lower at 8%, meaning 9 out of 10 submissions went through. As a result, Google deleted over 2 million apps for violating its terms and conditions — nearly half the number deleted in 2024. Meanwhile, Apple’s App Store Transparency Report shows that app removals more than doubled, to nearly 167,000, compared with over 82,500 in 2024.

Fraud (54%) and the removal of obsolete software (43%) were the primary drivers behind App Store deletions. Fraud-related removals were primarily associated with developers from China (13%), Pakistan (11%), the United States (11%), Turkey (11%), and Vietnam (8%).

According to the Google Play Annual Transparency Report, the most frequent reason for removals on their platform was data protection and privacy violations (44%). Other significant factors for Google Play included the distribution of ineligible goods, services, or content (35%), infringements on consumer information (13%), and instances of fraud or scams (5%).

You can read the report here: Google and Apple removed millions of apps in 2025

Guest Post: Pressing political topics reduce people’s vigilance against bots

Posted in Commentary with tags on May 19, 2026 by itnerd

More than 700 participants took part in a week-long experiment conducted by Surfshark and MSc students from Malmö University. Of them, 53% correctly identified more bots than they wrongly flagged humans as bots on the simulated social platforms. However, nearly half (47%) failed the task. A cybersecurity expert warns that the number of people unable to tell bots from real humans on social media will continue to grow rapidly.

“The ‘Bot or Not’ game and experiment help us keep connecting the dots and better understand the influence bad bots have on us, real social media users. Earlier this year, we found that major platforms remove over 6.3 billion fake accounts every year — roughly 47 times the annual number of babies born worldwide (around 135 million). Bots are being generated by the billions, and our latest experiment shows that half of the participants can no longer tell them apart from real people. This trend will accelerate, as the technology lets bots blend in seamlessly with real human profiles,” says Justas Pukys, Senior Product Manager at Surfshark.

When our emotions take over, bots thrive

The results of the recent social media bot experiment were eye-opening. The data suggests that engaging with sensitive political or social topics may reduce people’s ability to spot bots and make them more likely to falsely accuse real people.

The moment the “Bot or Not” simulation shifted to a more emotional tone, our participants’ bot-detection skills dropped. When the debate turned political and focused on immigration, participants’ bot-detection rate dropped to 54%, meaning that nearly half the social media bots slipped right past the players. Participants’ accuracy rate also declined to 63%, showing a spike in internet paranoia when participants accused humans of being bots.

The women’s rights topic presented the biggest bot-spotting challenges. The bot-detection rate crashed to 49%, meaning users missed more bots than they found. Worse, their accuracy rate fell to 61%, showing players most often accused real human content of being bot-generated.

“In comparison, while engaging in the data centers, a more technical debate for many, users performed the largest bot-detection rate of 71% (finding the majority of the bots), and a high (76%) accuracy rate. This suggests that when not directly emotionally triggered, we could detect more AI bots and are less likely to falsely accuse real humans,” explains Luís Costa, Research Lead at Surfshark.

The “Bot or Not” game is now online for everyone to play and take part.

Can we distinguish who is who on social platforms in the future?

“The experiment’s results are novel and significant. They suggest we can’t simply ‘read’ our way out of ‘botted’ social media. Bot-detection skills appear to be shaped by age, preferred platforms, and time spent on them. But the most striking finding was that our biggest blind spot is emotion: when debates get heated, it hijacks our digital radar.

To fight back against automated deception, we don’t need better textual analysis. We need a cooler head and a deeper awareness of our own vulnerabilities,” claims Luís Costa.

Justas Pukys, a cybersecurity expert at Surfshark, shares practical recommendations.

“Don’t forget to double-check the information you find on social media. Also, don’t take everything random users post at face value. Be careful when accepting and interacting with private messages that offer you prizes, invite you to click on strange links, or try to grab your attention with lines like ‘Your family member has been in an accident!’,” he advises.

The expert also highlights the importance of digital security hygiene, such as using anti-scam tools daily. They will help you analyze the content of emails, text messages, and websites and assess whether it has been generated by bots or other attackers.

This “Bot or Not” experiment inspired the launch of Surfshark’s Cybersecurity Advocacy Fund, which provides up to €100,000 in annual financial support distributed among students, researchers, and creative cybersecurity awareness initiatives worldwide. The upcoming application process will open in September 2026 — more information will follow.

METHODOLOGY

This bot-detection study analyzed data from 710 participants who played the interactive simulation “Bot or Not.” This machine and gameplay were created by Interaction Design students from Malmö University for the UNFOLD exhibition — a design competition for universities around the world during Milan Design Week, the world’s largest trade fair. Throughout the week-long public exhibition, visitors were invited to take part in the experiment.

Please find the full research methodology here.